AI Gateway vs API Gateway: Build LLM Middleware in Node.js
What an AI gateway does that an API gateway can't: model routing, semantic caching, token rate limits and failover, with TypeScript code for Node.js.
On this page 13 sections
Middleware used to mean an Express function that checked a JWT and logged the request. A request that ends in an LLM call needs more than that. Something has to pick the model, check the tenant’s token budget, redact the email address in the response and decide what to do after the third 429 in a minute. If a dedicated layer doesn’t do it, forty route handlers do, each slightly differently.
Quick answer
An AI gateway (also called an LLM gateway or AI middleware) sits between your app and model providers. It owns five jobs: model routing, caching, token-aware rate limiting, observability and failover. You need one once you call more than one model, serve more than one tenant, or get a bill you can’t explain.
AI gateway vs API gateway
| API gateway | AI gateway | |
|---|---|---|
| Unit of traffic | Requests | Tokens and requests |
| Reads the payload | No | Yes: prompts, completions, tool calls |
| Rate limiting | Requests per second | Tokens per minute + requests per minute |
| Caching | Exact key match | Semantic similarity |
| Routing | Path, header | Task difficulty, cost, provider health |
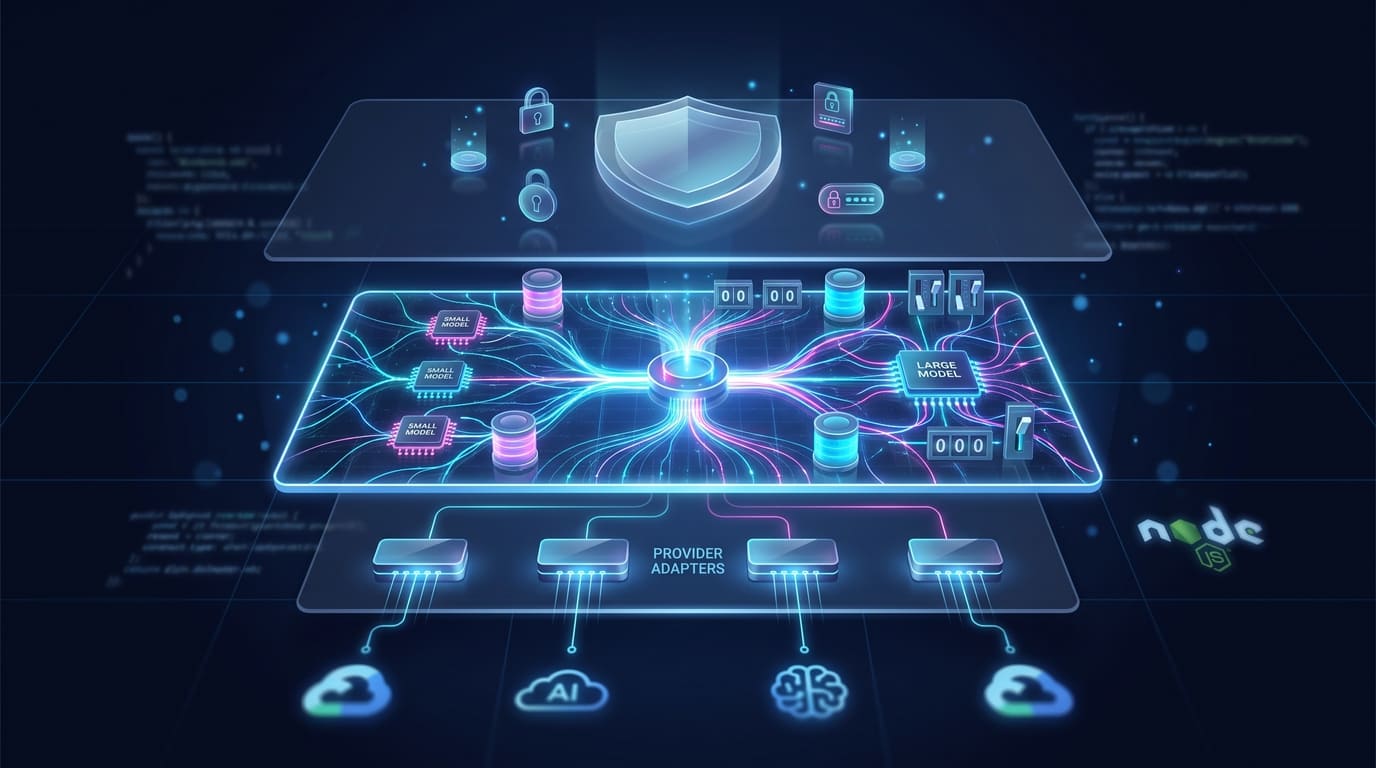
Keep the API gateway at the edge for auth and validation (the usual Express middleware patterns). The AI layer sits behind it, with a thin provider adapter underneath:
API gateway (auth, validation) → AI middleware (decisions) → provider adapter (SDK calls)Route handlers should never call a model ID directly. Once they do, you can’t change the model through config, attribute its cost or cache its responses.
1. Model routing
Most production traffic doesn’t need a frontier model. LMSYS’s RouteLLM cut costs by over 85% on MT Bench compared with sending everything to GPT-4, while keeping 95% of its quality score. Rules are enough for a first version:
type Tier = 'small' | 'frontier';

interface AIRequest {
  tenant: string;
  prompt: string;
  maxTokens?: number;
  requireCapability?: 'vision' | 'code' | 'reasoning';
}

function pickTier(req: AIRequest, inputTokens: number): Tier {
  if (req.requireCapability === 'reasoning') return 'frontier';
  if (inputTokens > 8_000) return 'frontier';
  return 'small';
}

// Ordered lists: primary model first, then fallbacks on other providers.
const MODELS: Record<Tier, string[]> = {
  small: process.env.MODELS_SMALL!.split(','),
  frontier: process.env.MODELS_FRONTIER!.split(','),
};
Log the tier on every call. A week of that data tells you whether a trained router would pay for itself.
2. Caching
Prompt caching is the cheap win. Anthropic charges up to 90% less for cached input reads, and OpenAI caches prompts over 1,024 tokens automatically. Keep the prefix stable: system prompt and tool definitions first, user content last, and no timestamps near the top.
Semantic caching skips the provider call when a new prompt means the same as one already answered. The similarity threshold decides everything. Prem AI’s measurements show 0.85 giving 45-70% hits but 15-30% wrong answers, while 0.93-0.95 gives around 30% hits with 3-7% wrong. Tune the threshold on your own labelled query pairs.
interface SemanticCache {
  // Keyed by tenant: a shared index will eventually serve one customer's answer to another.
  lookup(tenant: string, prompt: string): Promise<AIResponse | null>;
  store(tenant: string, prompt: string, res: AIResponse, ttlSec: number): Promise<void>;
}

function isCacheable(ctx: { usesTools: boolean; personalised: boolean }) {
  return !ctx.usesTools && !ctx.personalised; // "what's my balance?" must never hit the cache
}
A 20% hit rate on a $5,000 monthly bill saves $1,000 a month.
3. Token-aware rate limiting
Providers enforce tokens per minute (TPM) and requests per minute (RPM) at the same time. One 80,000-token job can be under the RPM limit and still block dozens of short chats. Use two buckets: reserve the worst case before the call, then correct it with real usage afterwards.
class TokenBucket {
  private tokens: number;
  private last = Date.now();
  constructor(private ratePerSec: number, private capacity: number) { this.tokens = capacity; }

  private refill() {
    const now = Date.now();
    this.tokens = Math.min(this.capacity, this.tokens + ((now - this.last) / 1000) * this.ratePerSec);
    this.last = now;
  }
  tryConsume(n: number) { this.refill(); if (this.tokens < n) return false; this.tokens -= n; return true; }
  adjust(n: number) { this.refill(); this.tokens = Math.min(this.capacity, this.tokens - n); }
}

export class DualBucketLimiter {
  private tpm: TokenBucket;
  private rpm: TokenBucket;

  constructor(tpmLimit: number, rpmLimit: number) {
    this.tpm = new TokenBucket(tpmLimit / 60, tpmLimit);
    this.rpm = new TokenBucket(rpmLimit / 60, rpmLimit);
  }

  acquire(estimatedInput: number, maxOutput: number): number | null {
    const reserved = estimatedInput + maxOutput;
    if (!this.tpm.tryConsume(reserved)) return null;
    if (!this.rpm.tryConsume(1)) { this.tpm.adjust(-reserved); return null; }
    return reserved; // returned, not stored, so concurrent requests can't overwrite it
  }

  reconcile(reserved: number, actualInput: number, actualOutput: number) {
    this.tpm.adjust(actualInput + actualOutput - reserved); // charge overruns, refund the rest
  }
}
Estimate input tokens with gpt-tokenizer or js-tiktoken, or use characters ÷ 4 as a fallback. Keep one limiter per tenant so a noisy tenant can’t use up a shared key. With more than one process, move the buckets to Redis: in-memory counters under cluster multiply the real limit.
4. Observability with OpenTelemetry
Use the OpenTelemetry GenAI semantic conventions so calls to OpenAI, Anthropic and local models share one schema. Note that v1.37.0 replaced gen_ai.system with gen_ai.provider.name.
import { trace, SpanStatusCode } from '@opentelemetry/api';

const tracer = trace.getTracer('ai-middleware');

function tracedCall(provider: ModelProvider, model: string, req: AIRequest, signal: AbortSignal) {
  return tracer.startActiveSpan(`chat ${model}`, async (span) => {
    span.setAttributes({
      'gen_ai.operation.name': 'chat',
      'gen_ai.provider.name': provider.name,
      'gen_ai.request.model': model,
      'app.tenant': req.tenant,
    });
    try {
      const res = await provider.complete(model, req, signal);
      span.setAttributes({
        'gen_ai.usage.input_tokens': res.usage.input,
        'gen_ai.usage.output_tokens': res.usage.output,
        'app.cost_usd': res.costUsd,
      });
      return res;
    } catch (err) {
      span.recordException(err as Error);
      span.setStatus({ code: SpanStatusCode.ERROR });
      throw err;
    } finally {
      span.end();
    }
  });
}
Redact PII before spans and logs leave the process (Pino redaction paths handle the log side). The agent and tool-call conventions are still marked Development, so pin your semconv version.
5. Resilience
Retry 408, 429, 5xx and timeouts. Never retry a 400, because it fails the same way every time. Give each attempt its own AbortSignal deadline, and stop calling a provider after repeated failures.
const RETRYABLE = new Set([408, 429, 500, 502, 503, 504]);
const sleep = (ms: number) => new Promise((r) => setTimeout(r, ms));

async function withRetry<T>(fn: (signal: AbortSignal) => Promise<T>, attempts = 3) {
  for (let i = 0; ; i++) {
    try {
      return await fn(AbortSignal.timeout(15_000));
    } catch (err: any) {
      if (err?.status !== undefined && !RETRYABLE.has(err.status)) throw err;
      if (i === attempts - 1) throw err;
      const base = 250 * 2 ** i;
      await sleep(base + Math.random() * base); // backoff with jitter
    }
  }
}

class CircuitBreaker {
  private failures = 0;
  private openedAt = 0;
  constructor(private threshold = 5, private coolDownMs = 30_000) {}

  canCall() { return this.failures < this.threshold || Date.now() - this.openedAt > this.coolDownMs; }
  success() { this.failures = 0; }
  failure() { if (++this.failures >= this.threshold) this.openedAt = Date.now(); }
}
Fall back across providers within the same tier. Don’t quietly downgrade a reasoning task to a small model; fail and say so.
Putting it together
class PolicyViolation extends Error {}
class RateLimited extends Error {}

export class AIMiddleware {
  private limiters = new Map<string, DualBucketLimiter>();
  private breakers = new Map<string, CircuitBreaker>();

  constructor(private providers: Map<string, ModelProvider>, private cache: SemanticCache) {}

  async complete(req: AIRequest, ctx = { usesTools: false, personalised: false }) {
    const violation = checkInputPolicy(req.prompt);
    if (violation) throw new PolicyViolation(violation);

    const cacheable = isCacheable(ctx);
    const hit = cacheable && (await this.cache.lookup(req.tenant, req.prompt));
    if (hit) return hit;

    const inputTokens = estimateTokens(req.prompt);
    const limiter = this.get(this.limiters, req.tenant, () => new DualBucketLimiter(200_000, 500));
    const reserved = limiter.acquire(inputTokens, req.maxTokens ?? 1024);
    if (reserved === null) throw new RateLimited();

    for (const model of MODELS[pickTier(req, inputTokens)]) {
      const breaker = this.get(this.breakers, model, () => new CircuitBreaker());
      if (!breaker.canCall()) continue;
      try {
        const res = await withRetry((signal) => tracedCall(this.providers.get(model)!, model, req, signal));
        breaker.success();
        limiter.reconcile(reserved, res.usage.input, res.usage.output);
        res.text = redactPII(res.text);
        if (cacheable) await this.cache.store(req.tenant, req.prompt, res, 3600);
        return res;
      } catch {
        breaker.failure();
      }
    }
    limiter.reconcile(reserved, 0, 0); // nothing consumed, return the budget
    throw new Error('No healthy provider');
  }

  private get<T>(map: Map<string, T>, key: string, make: () => T): T {
    if (!map.has(key)) map.set(key, make());
    return map.get(key)!;
  }
}
The Express route doesn’t know which model answered. The tenant comes from the verified JWT:
app.post('/api/chat', async (req, res, next) => {
  try {
    const answer = await ai.complete({ tenant: req.user.orgId, prompt: req.body.message, maxTokens: 800 });
    res.json({ text: answer.text });
  } catch (err) {
    if (err instanceof RateLimited) return res.set('Retry-After', '10').status(429).json({ error: 'Token budget exceeded' });
    if (err instanceof PolicyViolation) return res.status(422).json({ error: err.message });
    next(err);
  }
});
Agent middleware and MCP
Agent frameworks expose the same interception points inside the agent loop. LangChain 1.0 has before_model, after_model and wrap_model_call hooks; before_* hooks run in list order and after_* hooks run in reverse, as in Express. The Vercel AI SDK uses wrapLanguageModel:
import { wrapLanguageModel } from 'ai';
import type { LanguageModelV4Middleware } from '@ai-sdk/provider'; // V2 in AI SDK 5

const redactOutput: LanguageModelV4Middleware = {
  specificationVersion: 'v4',
  wrapGenerate: async ({ doGenerate }) => {
    const result = await doGenerate();
    return {
      ...result,
      content: result.content.map((p) => (p.type === 'text' ? { ...p, text: redactPII(p.text) } : p)),
    };
  },
};

const model = wrapLanguageModel({ model: baseModel, middleware: [cacheMiddleware, redactOutput] });
MCP doesn’t replace any of this. It is the wire protocol agents use to discover and call tools. Middleware decides whether a tool call should happen at all. Treat tool descriptions and results as untrusted input, for the reasons covered in indirect prompt injection.
Which AI gateway to use
| Gateway | Best at | Status in late 2026 |
|---|---|---|
| LiteLLM | 100+ providers, self-hosting | Active; PyPI releases 1.82.7 and 1.82.8 were hijacked on 2026-03-24, so pin versions and verify hashes |
| Bifrost | Throughput (~11µs overhead at 5,000 RPS, vendor-reported) | Active, Go |
| Portkey | Guardrails, governance, MCP gateway | Acquired by Palo Alto Networks |
| Vercel AI Gateway | Next.js and AI SDK apps | Active, managed |
| Helicone | Observability | Maintenance mode since March 2026; no new signups |
Start with one of these rather than the class above. Write your own layer only once you’ve outgrown them; by then you’ll know which of the five jobs you need to own.
Five mistakes to avoid
- Calling LLMs from route handlers. No cache, no limit, no cost tracking, no failover.
- Hardcoding one model ID. Model choice belongs in config.
- Sharing a semantic cache across tenants. Similarity search doesn’t check ownership.
- Retrying every error. A retried
400costs money and still fails. - Logging raw prompts. Redact before anything leaves the process.
Frequently Asked Questions
What is an AI gateway? A proxy between your app and LLM providers that routes, caches, rate-limits by tokens, applies guardrails and records cost per call. “LLM gateway” means the same thing.
Do I need one with a single provider? Not on day one. A thin wrapper like the one above covers budgets, retries and tracing. Add a gateway when you add a second provider or tenant.
How do I rate-limit LLM calls by tokens?
Use two buckets per tenant (TPM and RPM). Reserve estimated input plus max_tokens before the call and reconcile with real usage after it.
Is semantic caching safe? It is, with a threshold tuned on your own data, entries scoped per tenant, and no caching of personalised or tool-based answers.
Related reading
- Integrating AI and LLMs with Node.js. SDK basics, streaming and function calling.
- Indirect Prompt Injection Is a Backend Architecture Problem. Why tool input needs a policy gate.
- 7 Node.js Middleware Patterns for Express. The edge-layer patterns.
- Promise.all() Is Fine… Until It Isn’t. Capping concurrency when you fan out LLM calls.
- Node.js Error Handling Patterns. Which errors to surface and which to retry.